Vibe Coding for Startups: Savings vs. Technical Debt
Written by
Bhalli B
Full-Stack Engineer & SaaS MVP Architect
Vibe coding for startups saves the most money on repetitive implementation work (scaffolding, CRUD endpoints, form components, tests, and documentation) but creates technical debt when founders apply the same "accept and ship" workflow to authentication, billing, data migrations, or product-specific business logic. The tool is rarely the problem; the missing review gate is.
This guide gives you a risk-tier model for AI-generated code, a review checklist you can apply to every pull request, two production-grade code examples, a CI gate you can copy, and a rework-cost formula with worked numbers. The outcome: keep the speed on bounded work, cap every diff at roughly 500 changed lines, and spend human review hours only where the expected rework cost is highest.
1. Does vibe coding save money or create technical debt?
Vibe coding does both: it cuts implementation time on well-bounded tasks and raises downstream rework when code reaches production without a written specification, tests, and a reviewer who understands it. The deciding variable is not whether you use Claude Code, Cursor, or GitHub Copilot. It is whether your process treats AI output as a draft or as finished engineering work.
The reason is that AI changes where engineering time goes. In Faros AI's 2025 telemetry across more than 10,000 developers and 1,255 teams, high-adoption teams merged 98% more pull requests, but review time rose 91% and bugs per developer rose 9%. Generating code got cheaper; validating it became the bottleneck. That data comes from customer telemetry, so read it as an operational pattern across many teams, not as proof of cause.
In practice, this means: for a startup, the first six to eight weeks feel fast, and then every change requires reverse-engineering logic nobody fully understands. What this costs you if you get it wrong is not a visible outage. It is slow onboarding, repeated regressions, and a growing fear of touching core files.
What "vibe coding" actually means here
I use the term narrowly: a founder or engineer describes an outcome to an AI coding agent, accepts a large generated diff, and ships it with limited human understanding of the implementation. AI-assisted engineering is different. There the developer writes the specification, reviews the diff, owns the tests, and understands the system boundary being changed.
The first approach works for a weekend prototype. The second is the only version I would put in a SaaS product that handles user data, recurring billing, or a customer-facing workflow.
As a certified full-stack engineer who has architected SaaS MVPs from idea to launch, I treat AI output like a contractor's first draft: fast, useful, and never automatically trustworthy. The acceptance test is not "the model produced code." It is "the change meets the specification, passes the tests, and can be operated and rolled back in production."
2. Where do AI coding tools genuinely save startup money?
AI coding tools save the most money on low-ambiguity work that has a clear input, a clear output, and an existing pattern in your codebase to follow. The evidence is mixed outside that zone: in a GitHub controlled experiment with 95 developers, those using Copilot finished a bounded JavaScript task 55% faster, while METR's field trial of 16 experienced developers on 246 real tasks found they took 19% longer with AI tools, despite expecting a 24% speedup.
The gap between those two results is the whole story. Lab tasks arrive fully specified. Real work includes the specification and integration effort that lab tasks leave out. So the savings are real, but they concentrate where the task looks like a lab task.
The best candidates in an early-stage SaaS codebase:
- Scaffolding: Next.js route handlers, React Server Components, Zod schemas, Prisma models, typed API clients, and standard UI components.
- Tests for understood behavior: unit tests for a parser, integration tests for an existing endpoint, fixture-based tests for a billing calculation a human already specified.
- Repetitive migrations: adding a nullable column, creating an index, generating a CRUD resource, writing a seed file.
- Documentation and developer experience: README updates, OpenAPI descriptions, changelog drafts, comments on already-reviewed functions.
- Narrow refactors: renaming a field across a typed codebase, extracting a repeated component, or replacing a deprecated library call when tests already protect the behavior.
The economic logic is simple. These tasks have abundant public examples, small architectural consequences, and cheap verification. If an AI-generated CRUD endpoint is wrong, a failing test or a two-minute manual check exposes it before a customer does.
A concrete example: team invitations
Suppose a founder needs team invitations: create an invitation, email it, let the recipient accept it, add them to the workspace. An AI assistant can draft the /invitations route, the table and relations, the React form, the email template, and the Zod validation. That might save 10 to 20 hours of typing and boilerplate.
It should not decide what happens when an invitation expires, when the invitee already belongs to another workspace, when an owner downgrades the plan mid-invite, or when the same email is invited twice. Those are product rules, and product rules need a human owner.
The 70/30 rule
My operating rule for an MVP: let AI draft roughly 70% of routine implementation, and reserve human attention for the 30% that defines correctness: permissions, state transitions, money, privacy, data retention, and failure behavior. That does not mean reviewing 30% of the lines. It means spending disproportionate review time on the code that can cause an incident, a compliance problem, or a customer-trust failure.
3. Where does AI-generated code create real technical debt?
AI-generated code creates the most technical debt where correctness depends on context the model does not reliably have: your business rules, your data model, your threat model, and your production failure modes. A model can write syntactically valid authorization code and still get multi-tenant isolation wrong.
Security is the clearest example. A 2023 Stanford study by Perry et al. using OpenAI Codex found that AI-assisted participants wrote SQL-injection-vulnerable code 36% of the time, compared with 7% for the control group, and they rated their own code as more secure than the controls did. That study used an older model generation, so do not treat 36% as a current rate. Treat the pattern, confident but unverified output, as the lasting lesson. The OWASP Top 10 is the checklist of categories where that pattern becomes expensive.
| Risk area | Typical AI-draft failure | Why it becomes debt | Risk |
|---|---|---|---|
| Authentication and authorization | Role check covers one route but misses an API route, a deactivated member, or an expired session | Latent until someone exploits it | High |
| Payments and billing | Proration, tax, refunds, failed renewals, or plan changes computed incorrectly | Refunds, disputes, and manual reconciliation | High |
| Multi-tenant data access | A query without a workspace filter returns another customer's rows | One defect exposes many customers | High |
| Database migrations | Destructive change, or an index built without CONCURRENTLY that blocks writes | Downtime or data loss during deploy | High |
| Third-party integrations | Webhook retries, idempotency, and rate limits ignored | Fails only under real traffic | Medium |
| UI scaffolds, docs, test fixtures | Layout or copy mistakes, missing empty states | Cheap to see, cheap to fix | Low |
AI is good at the shape of these systems. It can draft a plausible middleware function, a Stripe webhook handler, or an access-control helper. The danger is plausibility without accountability. Never let an AI agent be the only thing that understands why a permission check, billing rule, or migration is safe.
The specification gap
Most bad AI code is not a failure to write code. It is an incomplete specification turned into a working-looking implementation very quickly. "Add a cancel subscription button" is not a specification. A real one answers:
- Can a user cancel during a trial, after payment, or after a downgrade?
- Does cancellation take effect immediately or at period end?
- What happens to annual discounts, pending invoices, and active seats?
- Who can cancel: owner, admin, billing contact, or all three?
- What does the audit log record?
- What should happen if Stripe is unavailable?
If those questions are unanswered, the AI picks defaults. Those defaults may be reasonable, but they are product decisions made by a system that carries no accountability for revenue, support load, or customer trust.
4. How should startups review AI-generated code?
Startups should review AI-generated code with a risk-tiered process: automate deterministic checks for every change, require a second human for business logic, and require named senior ownership for security, money, and architecture. A single "looks good to me" approval is not a review process.
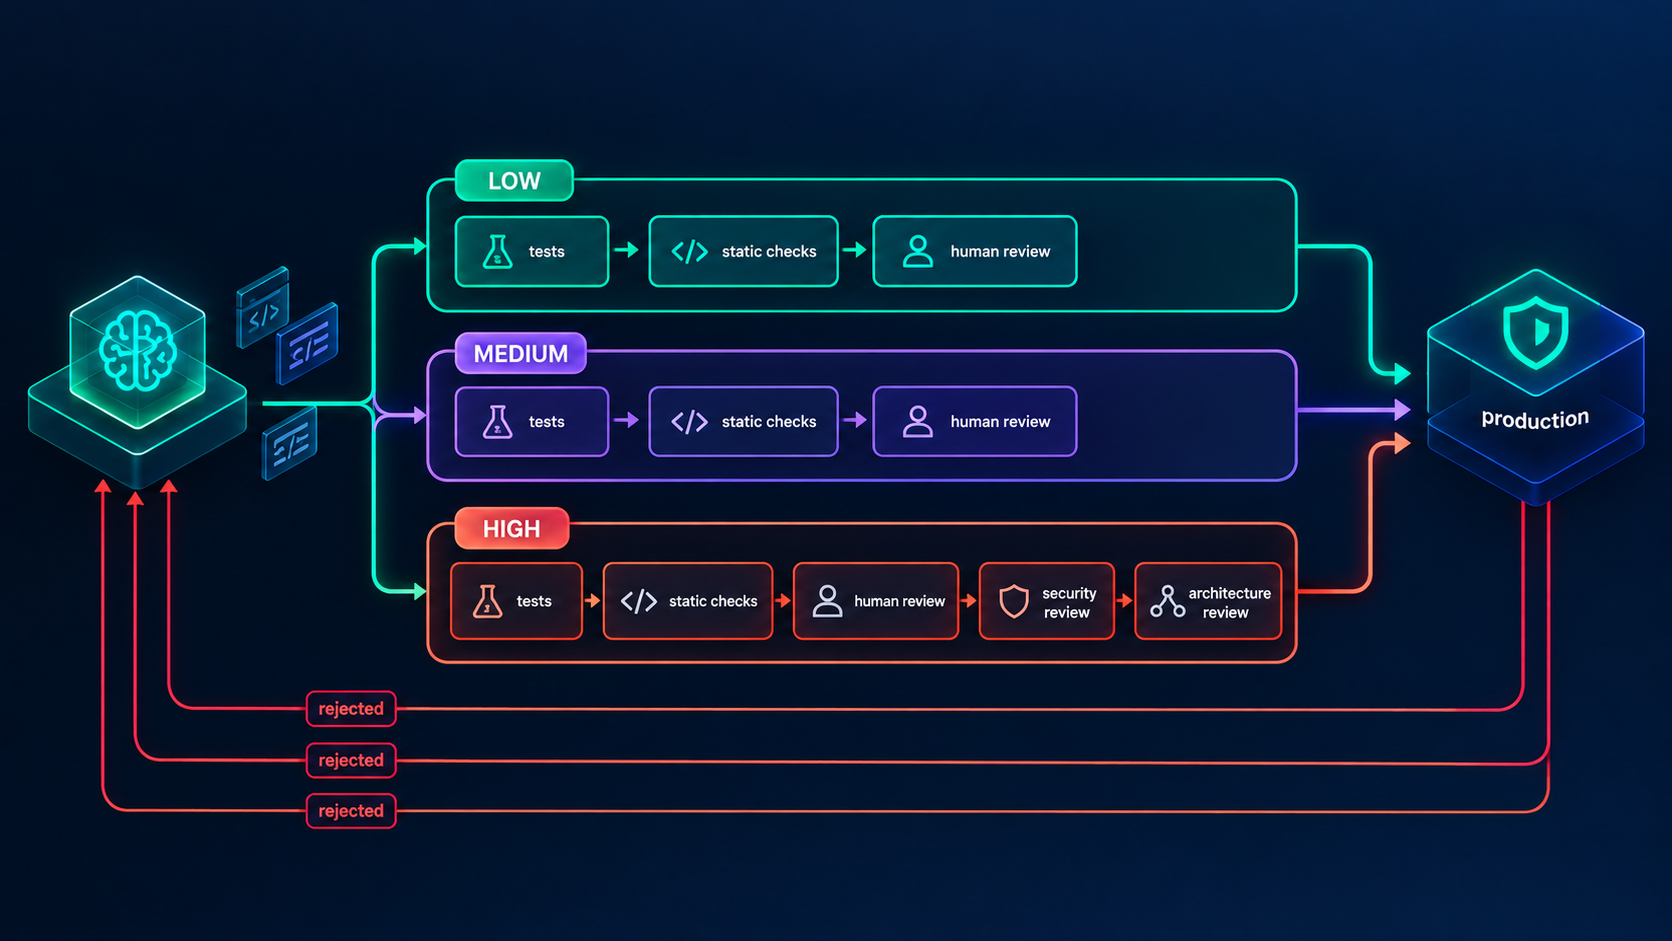 Figure 1: A risk-based review gate sends low-risk AI output through automated checks, while authentication, billing, and architecture changes also get human and security review, and rejected changes loop back to the AI assistant.
The three review tiers
The author labels every pull request low, medium, or high before requesting review. That label is the step most startups skip, and without it a button-color change and a billing change get the same shallow review.
| Tier | Example changes | Required checks | Reviewer | Merge rule |
|---|---|---|---|---|
| Low | UI scaffolds, copy, docs, test fixtures | Types, lint, unit tests, secret scan | Author self-review | Merge on green, diff under 500 lines |
| Medium | New CRUD endpoint, background job, read-only integration | Everything above, plus integration test and written acceptance criteria | One human who did not prompt the code | Merge after approval |
| High | Auth, billing, tenant queries, migrations, webhooks | Everything above, plus failure-path tests, dependency scan, and a rollback plan | Named senior owner via CODEOWNERS | Approval plus a feature flag |
The minimum review stack
Every AI-assisted pull request should clear these automated checks before a human spends time on it:
- Type checking: TypeScript strict mode or equivalent static validation.
- Linting and formatting: ESLint, Biome, or Prettier configured for your stack.
- Automated tests: unit tests for pure logic, integration tests for API behavior, end-to-end tests for critical journeys.
- Dependency and secret scanning: GitHub Dependabot, Snyk, Trivy, or GitGuardian.
- Diff-size limit: a 2,000-line AI-generated diff is not reviewable in any meaningful sense.
A practical review checklist
Before merging AI-generated code, ask:
- What business rule does this implement? If nobody can state it in one sentence, stop.
- What happens on invalid input? Check nulls, empty arrays, expired tokens, duplicate submissions, and malformed payloads.
- What data can this code read or write? Confirm tenant boundaries, field-level access, and retention rules.
- What happens when the external service fails? Stripe, Resend, Supabase, Twilio, and OpenAI all fail eventually.
- Is the operation idempotent? Webhooks, payment retries, and background jobs will run more than once.
- Does the test prove behavior or only execute code? Asserting that a function returns an object is weaker than asserting the correct state transition and the failure path.
- Can a new engineer understand this in 30 minutes? If not, add an architecture note or a simpler abstraction.
- What is the rollback plan? Especially for schema changes, feature flags, and third-party integrations.
Code guardrail: make billing intent explicit
This TypeScript pattern makes an AI-assisted billing change hard to merge casually. It validates input with Zod, enforces authorization on the server, returns the same 404 whether the workspace is missing or the caller has no rights (so it does not leak which workspaces exist), and is idempotent.
// src/lib/billing/cancel-subscription.ts
import { z } from "zod";
import { prisma } from "@/lib/prisma";
import { stripe } from "@/lib/stripe";
import { AppError } from "@/lib/errors";

const CancelSubscriptionInput = z.object({
  workspaceId: z.string().cuid(),
  requestedByUserId: z.string().cuid(),
  // "immediate" is a revenue and access decision, so the caller must state it.
  effectiveAt: z.enum(["period_end", "immediate"]),
  reason: z.enum(["customer_request", "policy_violation", "nonpayment"]),
});

export async function cancelSubscription(rawInput: unknown) {
  const input = CancelSubscriptionInput.parse(rawInput);

  // Authorization lives in the query: only an OWNER or BILLING_ADMIN of this
  // workspace can match, so a member of another workspace gets nothing back.
  const membership = await prisma.membership.findFirst({
    where: {
      workspaceId: input.workspaceId,
      userId: input.requestedByUserId,
      role: { in: ["OWNER", "BILLING_ADMIN"] },
    },
    include: { workspace: { include: { subscription: true } } },
  });

  const subscription = membership?.workspace.subscription;
  if (!subscription) {
    // Same response for "no such workspace", "not a member", and "wrong role".
    throw new AppError("NOT_FOUND", 404);
  }

  // Idempotency: a double-click or retry must not hit Stripe twice.
  if (
    subscription.status === "CANCELED" ||
    (subscription.status === "CANCEL_SCHEDULED" &&
      input.effectiveAt === "period_end")
  ) {
    return { subscriptionId: subscription.id, alreadyCanceled: true };
  }

  if (input.effectiveAt === "immediate" && subscription.status === "PAST_DUE") {
    throw new AppError("IMMEDIATE_CANCELLATION_BLOCKED_FOR_PAST_DUE", 409);
  }

  // Gotcha: cancel_at_period_end: false does NOT cancel anything. A plausible
  // AI draft passes it for "immediate" and silently cancels nothing in Stripe
  // while the database says CANCELED. Immediate cancellation needs cancel().
  const stripeSubscription =
    input.effectiveAt === "immediate"
      ? await stripe.subscriptions.cancel(subscription.stripeSubscriptionId)
      : await stripe.subscriptions.update(subscription.stripeSubscriptionId, {
          cancel_at_period_end: true,
        });

  await prisma.subscription.update({
    where: { id: subscription.id },
    data: {
      status:
        input.effectiveAt === "immediate" ? "CANCELED" : "CANCEL_SCHEDULED",
      canceledAt: input.effectiveAt === "immediate" ? new Date() : null,
      cancellationReason: input.reason,
    },
  });

  return {
    subscriptionId: subscription.id,
    stripeStatus: stripeSubscription.status,
    effectiveAt: input.effectiveAt,
  };
}
An AI can draft this in a minute. A human still has to decide whether BILLING_ADMIN should be allowed to cancel, whether immediate cancellation should refund prepaid time, and whether the Stripe webhook (customer.subscription.updated and customer.subscription.deleted) is the source of truth for final status. The Stripe subscription cancel documentation is where I verify the difference between scheduled and immediate cancellation before approving anything like this.
If you already have an AI-assisted codebase and are unsure which parts are safe to expand, book a 30-minute codebase risk review and I will help you classify the highest-risk areas before the next feature ships.
5. What does skipped AI-code review actually cost?
The real cost of skipped review is not the hours you saved. It is the probability that the defect survives, the cost to diagnose and fix it, and the business damage before someone does. A useful planning formula is:
D = H × M × P
The formula is deliberately conservative. It excludes churn, refunds, legal exposure, incident response, and reputation damage. Those costs are real but vary too much by product for one equation.
Worked example: authorization review skipped
A founder skips a 4-hour security review on an AI-generated workspace-permission change. There is a 60% chance the defect reaches production, and fixing it after release takes 16 hours (investigation, patch, tests, deployment, and an audit of affected records). So M = 16 ÷ 4 = 4.
Worked example: UI scaffold review skipped
AI generates a settings-page form. The founder skips a 1-hour detailed review, the defect has a 20% chance of reaching production, and the fix would take 2 hours. So M = 2 ÷ 1 = 2.
How to estimate P and M without guessing
Use your own history. Count how many AI-assisted pull requests in the last quarter produced a bug that escaped to production, per tier; that ratio is your P. For M, look at the time between "bug reported" and "fix deployed" for those escapes, and divide by the review time you would have spent. After one quarter you stop arguing about review depth and start reading a table. Until then, treat the numbers above as illustrations, not benchmarks.
The decision in one view: spend review effort where expected rework is high, not uniformly across every generated line.
6. Is "it works" enough to ship AI-generated code?
"It works" is not enough, because a passing happy path proves neither security, maintainability, operability, nor correctness under failure. The most expensive AI-generated code I review usually passes a smoke test while hiding a missing tenant filter, an unhandled webhook retry, or a state transition that corrupts billing data.
The pattern matches the research. While vibe coding speeds up initial output, recent research on AI-assisted coding shows that team review times and bug reports can spike significantly as projects scale. That is consistent with what I see in startup codebases: the first version of a feature arrives quickly, and the second, third, and fourth changes get expensive because the original was accepted without enough context.
The difference between a demo and a system
A demo answers one question: does this work when I do the expected thing? A production SaaS system must also answer:
- What happens when two users act at the same time?
- What happens when the database is slow or unavailable?
- What happens when a webhook arrives twice?
- What happens when a customer upgrades mid-cycle?
- What data is logged, retained, and visible to support?
- What happens when the person who wrote the feature leaves?
AI can help brainstorm answers to those questions. It should not answer them silently inside a merge.
Unreviewed versus reviewed authorization
An AI assistant generates a role check inside a page component. It works for the owner in the test workspace, but it does not cover API routes, deactivated members, or a user who belongs to two workspaces.
// Only the UI checks the role.
if (user.role !== "ADMIN") {
  return <NotAuthorized />;
}

return <DeleteWorkspaceButton workspaceId={workspaceId} />;
A UI check is a user-experience control, not an authorization boundary. Anyone who can call the API directly can still delete the workspace.
The same feature is scaffolded by AI, then hardened so authorization is enforced in the server action, with tests for owner, admin, member, and cross-workspace access.
// The UI can hide the button, but the server decides whether the action is allowed.
export async function deleteWorkspace(input: DeleteWorkspaceInput) {
  const session = await auth();
  if (!session) throw new AppError("UNAUTHENTICATED", 401);

  const membership = await getMembership(session.userId, input.workspaceId);

  // Same 404 for non-members and non-owners: do not reveal the workspace exists.
  if (membership?.role !== "OWNER") throw new AppError("NOT_FOUND", 404);

  await deleteWorkspaceRecord(input.workspaceId);
}
The AI still accelerated the first draft. Human review turned a plausible UI control into an enforceable security boundary.
7. How do you decide when to use vibe coding in an MVP?
Use vibe coding in an MVP when the task is reversible, testable, low-risk, and follows an existing architectural pattern; avoid relying on it for irreversible decisions, security boundaries, financial calculations, or core domain logic. The goal is not to ban AI. It is to stop it from making decisions that should have a named human owner.
A five-question decision framework
Certified in building MVPs, I run these five questions before accepting any large AI-generated change:
- Is the requirement written down? If acceptance criteria do not exist, the AI is inventing product policy.
- Can the change be tested automatically? If not, write a manual test script or do not ship it yet.
- Does it cross a trust boundary? Authentication, authorization, payments, personal data, third-party data, and infrastructure changes need stricter review.
- Is the diff small enough to understand? If a reviewer cannot explain it in five minutes, split it.
- Who owns the consequence in production? Every high-risk change needs a named person responsible for monitoring, rollback, and incident response.
If the answer to question 1, 3, or 5 is "no," the next step is not more prompting. It is a short specification and a review plan.
Tooling choices that reduce debt
For a SaaS MVP I commonly use:
- Next.js and TypeScript for a typed boundary between UI, API, and data access (see why I choose Next.js for MVPs).
- PostgreSQL with Prisma or Drizzle for explicit schemas and migration history.
- Zod for runtime validation at every external boundary.
- Playwright for critical user journeys, not just component rendering.
- GitHub Actions for type checks, tests, linting, dependency scanning, and preview deployments.
- Feature flags so a bad AI-assisted change can be disabled without a redeploy.
One migration gotcha worth knowing: PostgreSQL refuses CREATE INDEX CONCURRENTLY inside a transaction block, so a migration tool that wraps every file in a transaction will fail on exactly the statement that keeps writes unblocked. AI drafts often use the plain CREATE INDEX instead, which takes a lock that blocks writes on the table for the duration of the build. Test every AI-drafted migration against a copy of production-sized data before it ships.
If you are weighing how much of this to do yourself versus hand off, the trade-offs are in what AI tools change about SaaS MVP cost, and Hire a SaaS MVP developer lists the fixed-scope tiers I work in.
8. What process prevents vibe-coding debt without slowing the team down?
The process that prevents vibe-coding debt is small specifications, small pull requests, risk-tiered review, automated verification, and explicit ownership, not slower coding. Spend human attention on decisions, not on retyping boilerplate.
Enforce the tiers in CI, not in good intentions
Policy that depends on remembering will fail by the third sprint. Two small files make the high-risk tier real. First, CODEOWNERS routes anything touching money, auth, or schema to a named owner:
# .github/CODEOWNERS
/src/lib/billing/    @your-github-handle
/src/lib/auth/       @your-github-handle
/prisma/migrations/  @your-github-handle
Second, a GitHub Actions job fails any pull request that touches those paths without a risk:high label, or that adds more than 500 lines. Turn on "Require review from Code Owners" in branch protection so the label cannot be a rubber stamp.
# .github/workflows/risk-gate.yml
name: risk-gate
on:
  pull_request:
    types: [opened, synchronize, labeled, unlabeled]

jobs:
  classify:
    runs-on: ubuntu-latest
    permissions:
      contents: read
      pull-requests: read
    steps:
      - uses: actions/checkout@v4
        with:
          fetch-depth: 0
      - name: Enforce risk label and diff size
        env:
          LABELS: ${{ join(github.event.pull_request.labels.*.name, ',') }}
          BASE_SHA: ${{ github.event.pull_request.base.sha }}
          HEAD_SHA: ${{ github.event.pull_request.head.sha }}
        run: |
          set -euo pipefail
          CHANGED=$(git diff --name-only "$BASE_SHA" "$HEAD_SHA")

          # High-risk paths require an explicit label, which triggers CODEOWNERS review.
          if echo "$CHANGED" | grep -qE '^(prisma/migrations/|src/lib/billing/|src/lib/auth/|src/middleware\.ts)'; then
            if ! echo "$LABELS" | grep -q 'risk:high'; then
              echo "::error::High-risk paths changed. Add the risk:high label."
              exit 1
            fi
          fi

          # Cap diff size so a human can actually review it.
          ADDED=$(git diff --shortstat "$BASE_SHA" "$HEAD_SHA" | grep -oE '[0-9]+ insertion' | grep -oE '[0-9]+' || echo 0)
          if [ "$ADDED" -gt 500 ]; then
            echo "::error::$ADDED lines added. Split this PR (limit: 500)."
            exit 1
          fi
A weekly operating checklist
- Before building: write acceptance criteria, edge cases, and non-goals in the issue.
- During building: keep AI-generated changes under roughly 500 changed lines.
- Before review: run type checks, tests, linting, and security scans locally.
- During review: classify the tier and require the matching reviewer depth.
- Before merge: confirm rollback, monitoring, and ownership.
- After release: track escaped defects, review wait time, change failure rate, and hours spent on rework.
- Monthly: find the three files that generate the most incidents and refactor or document them.
Common mistakes I see in AI-assisted startup codebases
- One giant prompt, one giant diff. The reviewer cannot verify what they cannot hold in their head, so approval becomes a formality.
- The same model writes the code and the tests. Tests that mirror the implementation's assumptions pass even when the assumption is wrong. A human writes at least the failure-path cases.
- Coverage mistaken for confidence. Coverage can rise while behavioral testing stays shallow.
- No owner for high-risk files. When everyone can change billing code, nobody is accountable for it. This is also the moment many founders start asking about a fractional CTO: the gap is rarely typing speed, it is a named person who owns risk.
- Treating AI-written docs as truth. Generated READMEs describe what the code was supposed to do, so verify them against behavior.
- Skipping rollback for "small" schema changes. An additive column is reversible; a column type change on a large table usually is not.
The teams that succeed with AI are not the ones prompting hardest. They make review capacity, test depth, and ownership explicit before code volume grows.
9. Conclusion and Actionable Roadmap
Vibe coding for startups is neither a free productivity win nor an automatic source of technical debt. It is a leverage decision: use AI aggressively for scaffolding, tests, migrations, and repetitive implementation, and require a written specification, tests, and risk-proportionate human review for authentication, billing, multi-tenant data access, and core business logic.
The practical outcome is a team that keeps most of the speed benefit while avoiding the classic pattern of rapid output for two months followed by a codebase nobody can safely change. Start with the three tiers, enforce them in CI, keep diffs under 500 lines, and make one person accountable for every high-risk change.
Build fast without inheriting a codebase you cannot safely change: I help founders and technical teams turn AI-assisted development into a controlled SaaS delivery process using Next.js, TypeScript, PostgreSQL, Prisma or Drizzle, Stripe, and production-grade review workflows. Contact me today to book a 30-minute AI-codebase risk audit.