Building a GitHub README Generator: Architecture Breakdown
Written by
Bhalli B
Full-Stack Engineer & SaaS MVP Architect
Certified Full-Stack Developer & MVP Specialist · Lahore, Pakistan
Every GitHub profile README generator has to solve the same three architectural problems before a single line of markdown gets exported: proxying and caching GitHub's REST API without burning through a 5,000-requests-per-hour authenticated rate limit, generating stats visuals server-side fast enough that the editor feels instant, and - if you're adding an AI layer - keeping a non-deterministic model's output inside a strictly deterministic markdown pipeline. I hit all three building GPRG, an open-source README generator with a built-in Gemini-powered bio writer, and this post is the architecture I landed on after the naive version fell over in the first week of real traffic.
1. Why Does a README Generator's Real Bottleneck Live in the GitHub API, Not Your Own Server?
The bottleneck isn't your Next.js app - it's GitHub's REST API rate limit, which caps authenticated requests at 5,000 per hour per token and unauthenticated requests at 60 per hour per IP, and every stats card, contribution streak, and top-languages widget in a generator requires at least one call to /users/{username}/repos or the GraphQL API's contribution calendar.
I shipped GPRG's first stats-card version making a live API call on every single page load of every user's generator session, with no caching layer at all. It worked fine in testing with three users. It fell over in production the first time GPRG got shared in a dev community thread - dozens of simultaneous sessions each triggering 3-4 GitHub API calls, and the shared server-side token hit its 5,000/hour ceiling well before the hour was up, returning 403 responses to everyone, including users whose data had nothing to do with the spike.
// app/api/github-stats/route.ts
// The fix: an edge-cached proxy in front of every GitHub API call,
// keyed by username + stat type, so ten users looking at the same
// profile in one hour cost GitHub's rate limit exactly one request.
import { NextRequest, NextResponse } from "next/server";

export const runtime = "edge";

const CACHE_TTL_SECONDS = 60 * 60; // 1 hour - GitHub stats don't change
// fast enough to justify a shorter window, and this is the single
// biggest lever against rate-limit exhaustion.

export async function GET(req: NextRequest) {
  const username = req.nextUrl.searchParams.get("username");
  if (!username) {
    return NextResponse.json({ error: "username required" }, { status: 400 });
  }

  const res = await fetch(`https://api.github.com/users/${username}`, {
    headers: {
      Authorization: `Bearer ${process.env.GITHUB_TOKEN}`,
      "X-GitHub-Api-Version": "2022-11-28",
    },
    // Next.js's fetch cache respects this directly on Edge runtime -
    // repeat requests for the same username within the TTL never
    // touch GitHub's API at all.
    next: { revalidate: CACHE_TTL_SECONDS },
  });

  if (res.status === 403) {
    // Rate-limit hit on OUR token, not the user's fault - surface a
    // distinct error so the client doesn't show "user not found."
    return NextResponse.json(
      { error: "Stats temporarily unavailable, please retry shortly." },
      { status: 503 }
    );
  }

  const data = await res.json();
  return NextResponse.json(data, {
    headers: { "Cache-Control": "public, s-maxage=3600, stale-while-revalidate=600" },
  });
}
// Client component calling GitHub directly
const res = await fetch(
  `https://api.github.com/users/${username}`,
  { headers: { Authorization: `token ${TOKEN}` } }
);
Ships your GitHub token in the client bundle (a public security exposure) and gives every visitor's browser its own uncached call against the same shared rate limit.
// Client component calling YOUR edge route instead
const res = await fetch(`/api/github-stats?username=${username}`);
Token stays server-side, and the edge cache means ten concurrent viewers of the same profile cost GitHub's API exactly one request per hour instead of ten.
2. What's the Real Rate-Limit Math Behind a Caching Layer?
C = L / (R × (1 - H))
3. How Do You Keep an AI-Generated Bio From Breaking a Deterministic Markdown Pipeline?
The risk with adding Gemini into GPRG's bio generator wasn't output quality - it was output shape. A markdown pipeline that assembles a README from fixed sections (badges, stats, bio) breaks the moment one section returns unpredictable formatting: stray headers, inconsistent line counts, or markdown syntax the model injects into what's supposed to be plain body text.
I solved this the same way I approach scope control on any client MVP - as a Certified Project Manager, I treat "the model might return anything" as a hard requirement to design around, not an edge case to patch later. GPRG's prompt explicitly forbids headers and constrains line count, and every response gets passed through a sanitizer before it's allowed into the editor state.
// lib/sanitize-bio.ts
// Runs on every Gemini response before it touches the editor's
// markdown state - treats the model's output as untrusted input.
export function sanitizeBio(raw: string): string {
  return raw
    // Strip any markdown headers the model added despite instructions -
    // headers inside a bio section break the README's heading hierarchy.
    .replace(/^#{1,6}\s.*$/gm, "")
    // Collapse more than 2 consecutive blank lines, which Gemini
    // occasionally produces when a prompt yields a shorter response.
    .replace(/\n{3,}/g, "\n\n")
    // Cap at 8 lines - anything longer means the model ignored the
    // 4-6 line instruction, and a bio that long breaks the layout
    // of every template that places it above the stats grid.
    .split("\n")
    .slice(0, 8)
    .join("\n")
    .trim();
}
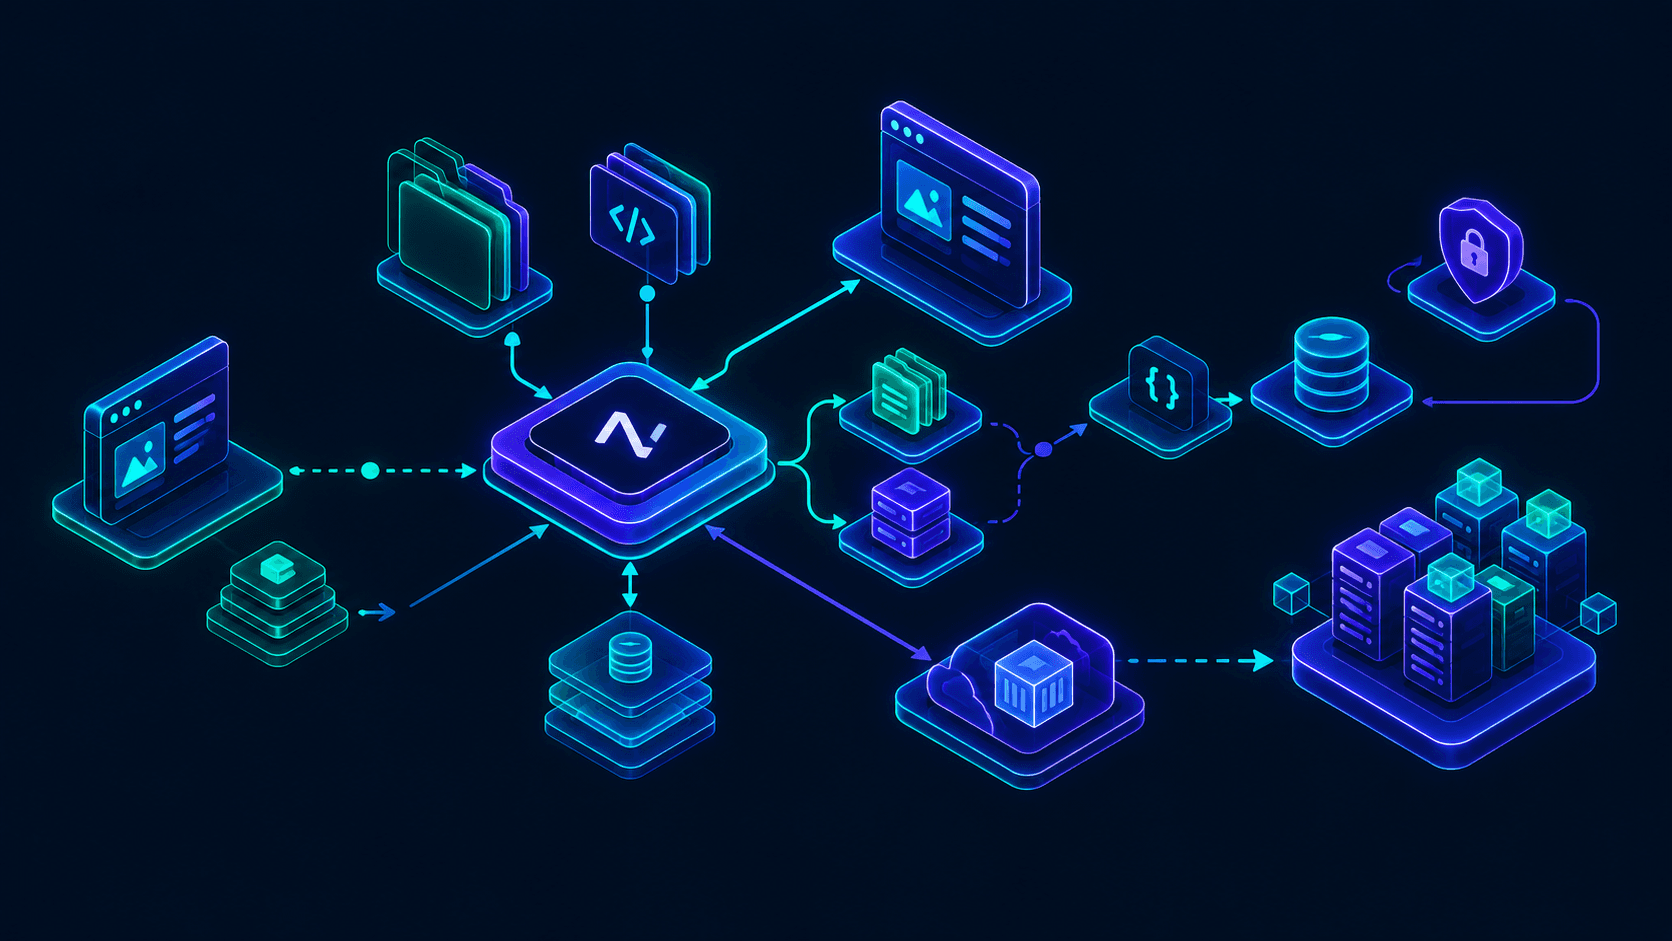
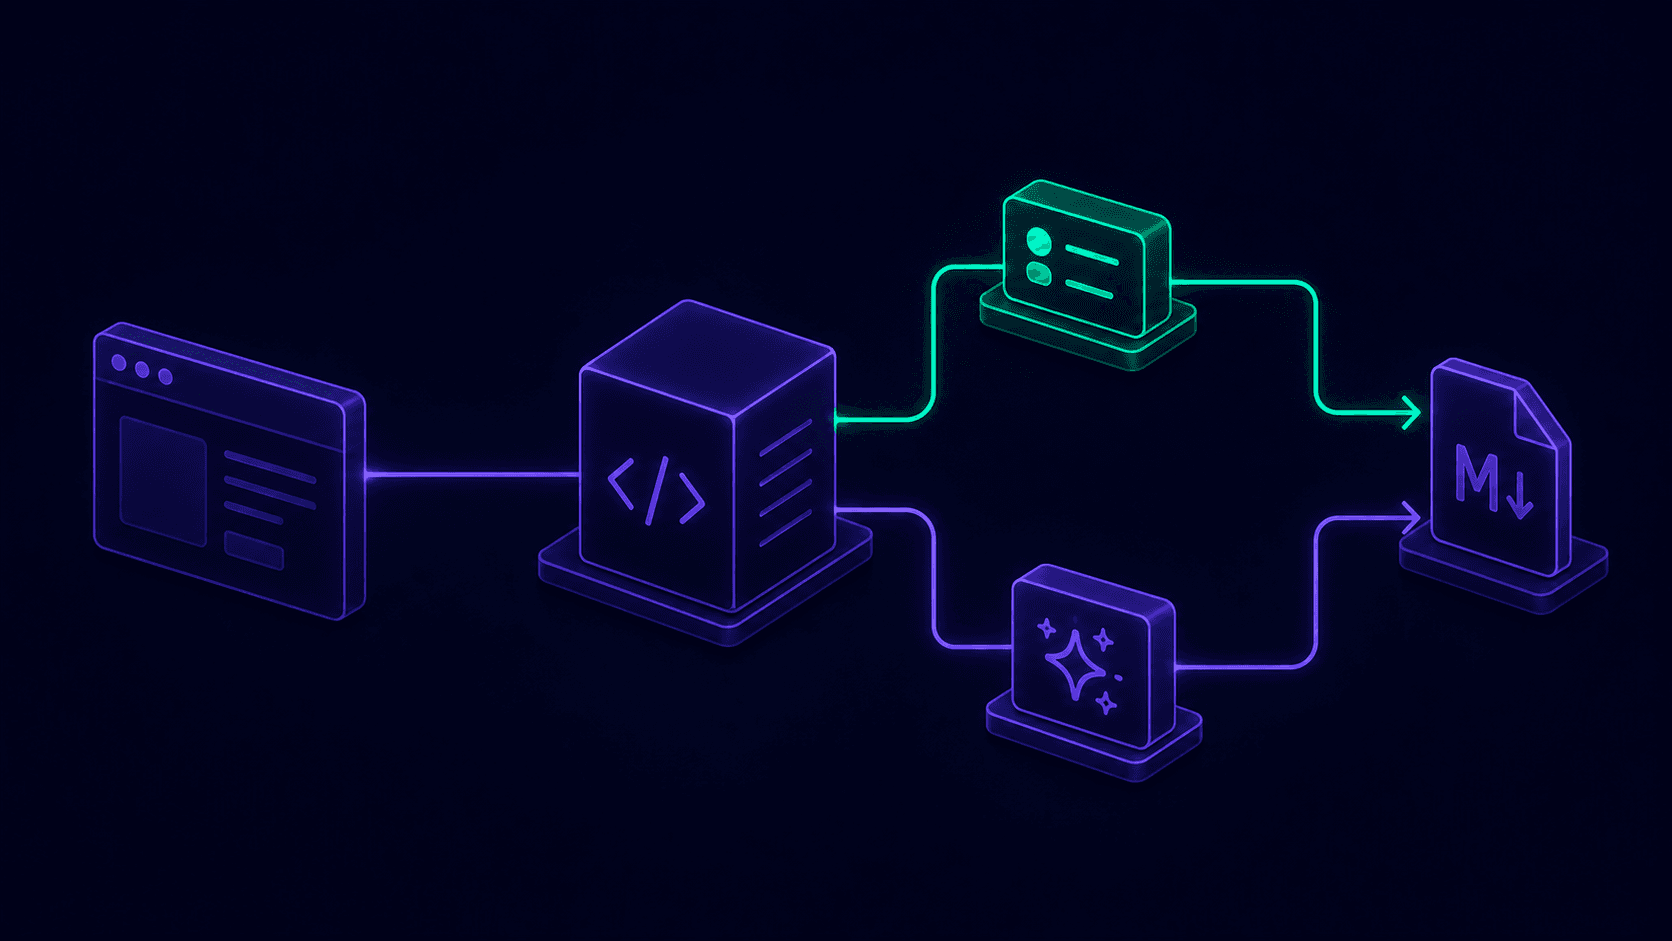
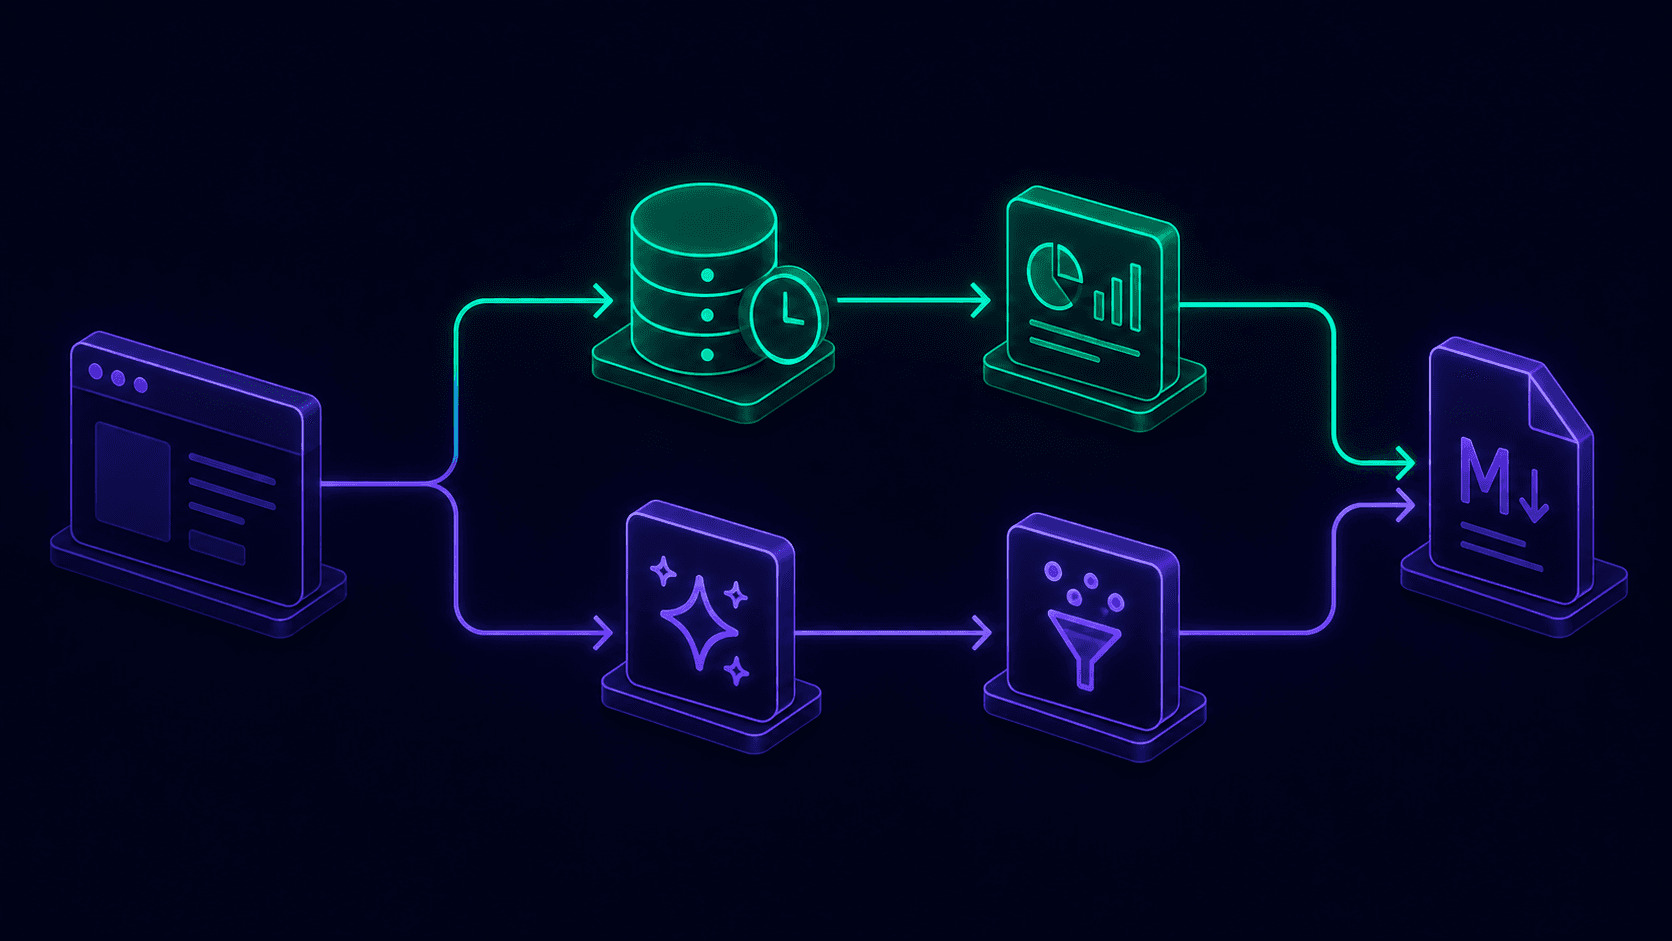 Figure 1: The two independent data paths - cached GitHub API stats and sanitized Gemini bio output - that converge into a single markdown assembly step before export.
4. Which Architecture Pattern Should You Actually Choose for Stats Visuals?
| Pattern | Rate-Limit Exposure | Freshness | Best For |
|---|---|---|---|
| Uncached client-side fetch | Severe - one call per viewer | Real-time | Never, in production |
| Server-cached edge proxy (GPRG's approach) | Low - shared cache per username | Up to 1 hour stale | Interactive editors with live previews |
| Pre-rendered static SVG, rebuilt on a cron | Lowest - batch job only | Hours to a day stale | Embedded badges viewed thousands of times (README images) |
GPRG's final README export actually combines the second and third patterns: the live editor uses the cached edge proxy for instant previews, but the embedded stats-card image URL that ships in the exported markdown points to a separately cached SVG endpoint designed to absorb thousands of README page loads across GitHub itself without ever touching the interactive editor's cache budget.
5. Conclusion and Actionable Roadmap
The architecture problem underneath any GitHub-data tool is never "how do I call the API" - it's "how do I make ten thousand people looking at overlapping data cost the rate limit close to nothing," and every other decision (SVG generation, AI sanitization, template rendering) sits downstream of getting that caching layer right first. GPRG went from a 403-erroring generator under its first real traffic spike to a stable, open-source tool serving tens of thousands of profile exports by fixing exactly that layer, then layering the Gemini bio generator on top of it with the same "treat external input as untrusted" discipline.
Need this same rigor applied to your own product's third-party API integration? I design and ship production SaaS MVPs - caching layers, AI feature integration, and the architecture decisions that hold up once real users show up - on the same Next.js/Node stack behind GPRG. Contact me today to book a 30-minute architecture review.